2026 INDEPENDENT INFRASTRUCTURE & AI BENCHMARK • 207+ TOOLS INDEXED
Open-Source Infrastructure, Databases & AI DevTools Leaderboard
Independent empirical benchmarks across p50/p99 latency, memory footprint, data privacy posture, and cloud vs. self-hosted TCO across 134 infrastructure, database, and AI developer categories.
Unhardened AI Repo Anti-Patterns & Token-Bloat Hall of Shame (Sorted by Score)
Repositories and default configurations failing our 4-pillar empirical rig on token bloat, missing CLAUDE.md boundaries, unpinned MCP schemas, or leaked credentials. Fix any repo in 60 seconds with the $9.99 9-File .ZIP or $49 Verified Hardening Kit.
Don’t see a tool in the top 207? Scan any GitHub repository in 3 seconds.
3s Live GitHub Repo Audit + Trust ScorecardStep 1: Enter owner/repo or tap a preset
1-Tap Presets:
Please enter a GitHub repository in owner/repo format (for example: langchain-ai/langchain or crewAIInc/crewAI), or tap one of the 1-tap popular repos below.
Step 1 of 3: Fetching live GitHub repository metadata & commit cadence...
Step 2 of 3: Auditing CI/CD test gates, issue backlog & dependency pinning...
Step 3 of 3: Production Readiness & Trust Scorecard Ready!
Watch Case Study: How a 5-Engineer Team Cut AI Tool Spend from $1,420/mo to $188/mo (4-Step Walkthrough)Click to expand ▾
Marcus Chen • 5-Seat AI Engineering StackTHE $1,420/MO AI BILL SHOCK
“Our 5-person startup just got hit with a $1,420 monthly bill for Cursor seats and unrouted Claude API calls.”
Three weeks into our sprint, finance flagged our corporate card: $40/seat for overlapping coding IDEs plus $1,140 in raw frontier API overages because every agent turn was rescanning our entire monorepo from scratch.
“We were paying $1,420 a month just to watch our agents re-read node_modules and lockfiles on every prompt.”
MONTHLY 5-ENGINEER AI TOOLING INVOICE
$1,420/mo 620% Overage
$280/mo overlapping IDE seats • $1,140/mo unpruned frontier API burn
Priya Patel • Founding AI Engineer14 CONFLICTING GITHUB REPOS
“So we tried wiring up open-source tools ourselves, and drowned in 14 conflicting GitHub repos and 38k-token prompts.”
Every X thread hyped a different agent framework, router, or vector DB. Without a compiled CLAUDE.md context tree or a 65/35 semantic router, every simple bug fix sent 38,400 unpruned tokens straight to our most expensive model.
“One thread said LangGraph, another said CrewAI, and nobody warned us about 38,000 discovery tokens per turn.”
“Wait... one of our dependencies is viral AGPL-3.0, and running two Electron agents just froze our 16GB MacBooks?”
Right before our enterprise SOC2 audit, legal flagged an AGPL-3.0 copyleft package inside our memory layer that would contaminate our proprietary repo, plus an unverified MCP server leaking customer code to the cloud.
“One hidden AGPL-3.0 dependency or cloud-egress MCP server can block an enterprise SOC2 deal overnight.”
Marcus Chen • 5-Seat AI Engineering StackHOW PULSEFORGE SOLVED IT
“That’s where PulseForge came in. In 60 seconds, we curated our 6-slot stack and cut our bill from $1,420 to $188/mo.”
We skipped the 6 slots we didn’t need, locked in 100% MIT/Apache tools that fit our 16GB laptops, and exported our compiled CLAUDE.md, docker-compose.ai-stack.yml, and 65/35 router, saving $1,232 every single month.
“6 curated slots, 6 omitted by design, 100% MIT/Apache clean, and $1,232/mo saved on Day 1.”
PULSEFORGE 60-SECOND STACK RESCUE
$188/mo Net Saved $1,232/mo
9.4k Pruned Context • 65/35 Router • 9-File Production .ZIP
Interactive 12-Slot AI Stack Studio•+ Add to Stack on Every Tool•Hardware VRAM, Power & SPDX License Audit
$935 to $1,232/mo Saved
ON A 5-SEAT ENGINEERING STACK ($188 to $485/MO CURATED BOM VS. $1,420/MO SAAS SPRAWL)
65 / 35 Token Routing
PACED FOR CONTEXT CACHING & FAST AST DIFFS SO YOU NEVER BURN FRONTIER QUOTA ON BOILERPLATE
12 Slots + 207 Tools
EMPIRICALLY AUDITED ACROSS 134 CATEGORIES & 217 HEAD-TO-HEAD SHOOTOUTS
AI Coding IDE & EditoriWhat Socket 01 DoesYour primary code editor for inline AI diffs, multi-file edits, and tab autocomplete.Essential for daily interactive coding • Skip only for headless server pipelines.
● Seated
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 02Core Layer • CLI Agent
Autonomous Terminal & SWE AgentiWhat Socket 02 DoesAutonomous terminal agent that plans, edits across your repo, runs tests, and commits.Best for multi-file refactors & PR automation • Optional if you only use an IDE.
● Seated
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 03Core Layer • Context OS
Agent Harness & Context OSiWhat Socket 03 DoesCompresses repo context (CLAUDE.md / AST maps) so agents stop re-reading junk files.Recommended for all stacks • Cuts per-turn prompt token waste by 40% to 75%.
● Seated
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 04Core Layer • Cost Router
LLM Gateway, KV-Cache & FinOps RouteriWhat Socket 04 DoesRoutes simple prompts to fast/cheap models and caches repeated context (65/35 cascade).High-ROI FinOps layer • Cuts monthly frontier API bills by ~58%.
● Seated
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 05Core Layer • Orchestrator
Multi-Agent Orchestration & State GraphiWhat Socket 05 DoesCoordinates multi-step agent workflows, tool handoffs, and typed state graphs.Use when chaining multiple agents/tools • Skip for single-agent coding.
○ OPTIONAL • NOT NEEDED
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 06Core Layer • Schema Out
Structured Output & Schema CompileriWhat Socket 06 DoesForces LLM outputs to strictly match your JSON/Pydantic types with zero parse crashes.Essential for production APIs & tool calling • Skip for plain chat outputs.
● Seated
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 07Expansion • Vector RAG
Agent Memory, Vector & Hybrid RAG EngineiWhat Socket 07 DoesStores embeddings and indexes docs/code for fast semantic retrieval (RAG) & memory.Use when querying large docs or customer knowledge bases • Skip for small repos.
○ OPTIONAL • NOT NEEDED
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 08Expansion • Sandbox VM
Code Sandbox, MicroVM & Browser RuntimeiWhat Socket 08 DoesIsolated MicroVM or headless browser where agents safely execute untrusted code.Required if agents run user-generated code or scrape live web pages.
○ OPTIONAL • NOT NEEDED
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 09Expansion • MCP Firewall
MCP Server Runtime & Tool-Poisoning FirewalliWhat Socket 09 DoesInspects MCP tool servers to block prompt injection, tool poisoning, and data leaks.Recommended whenever connecting third-party MCP servers to your IDE or agent.
○ OPTIONAL • NOT NEEDED
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 10Expansion • OWASP CI Gate
50-Probe OWASP Red-Team & Regression CI GateiWhat Socket 10 DoesAutomated GitHub Actions gate that scans commits for leaked secrets and OWASP LLM flaws.Essential before shipping to production or passing SOC2 security review.
● Seated
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 11Expansion • Voice Pipeline
Voice, WebRTC & Realtime Multimodal AgentiWhat Socket 11 DoesUltra-low-latency WebRTC audio pipeline for real-time voice agents and speech-to-speech.Only needed if your product has live voice/audio features • Safe to skip otherwise.
○ OPTIONAL • NOT NEEDED
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
Socket 12Expansion • Local GPU
Local Inference & QLoRA / GRPO Fine-Tune EngineiWhat Socket 12 DoesRuns open-weight LLMs (Llama, Qwen, DeepSeek) locally on your GPU with zero cloud egress.Use for air-gapped privacy or zero-API-cost local inference on 16GB+ VRAM.
○ OPTIONAL • NOT NEEDED
+ Add a tool that is not listed
We cannot check unlisted tools for license or speed. We use your answers for the cost and privacy checks, and list it by name in your export.
3
Review and export your stack
Plain-English verdict, live architecture summary, and your 9-file production config bundle for the slots seated above.
Checking your stack...
Technical details RAM, GPU memory, license and budget checks behind the summary above
• Hardware Fit Verified: 459 MB RAM & 0.0 GB VRAM fits inside your 24 GB GPU envelope.
[+] Maintainer / DevTool Founder: Test & Verify Your Repository in Any of the 12 BOM SlotsPreview Compatibility & Claim Slot Placement ▾
Preview how your tool pairs with upstream/downstream stack layers, or verify your repository's p50 latency, RAM, and license telemetry for default slot placement.
We replace overlapping SaaS subscriptions and hallucinated chat configs with empirical benchmark telemetry, hardware-matched VRAM sizing, and ready-to-commit deployment files.
01
Curate or Click "+ Add to Stack"
Click + Add to Stack on any tool in our leaderboard, /vs/ shootouts, or /alternatives/ pages to slot it directly into your persistent 12-Slot Stack Bag.
Auto-maps to Slots 01 to 12
02
Set GPU Power & Scenario
Pick a 1-click Scenario Setup (Minimal 3-Slot CLI, Solo Indie Lean, Enterprise SOC2, or Local GPU) and select your available VRAM and compute routing profile.
Skip any slot you don't need (YAGNI)
03
Audit VRAM, License & TCO
Our live architectural coach flags VRAM bottlenecks, AGPL-3.0 copyleft contamination, HIPAA cloud egress leaks, and 1-click FinOps arbitrage swaps.
Real-time hardware & budget fit
04
Export 9-File BOM & Board ADR
Unlock your starter CLAUDE.md free ($0 via email), grab the $4.99 3-File Config Pack, or download the complete $9.99 9-File production .ZIP bundle with ADR-2026-AI-STACK.md and CI security gates.
Ready to commit in 60 seconds
Free live preview • Instant GPU VRAM, SPDX license & 65/35 router math
3 REAL PRODUCTION SCENARIOS
How the math adapts to your hardware & team.
Three verified stack receipts across a 5-seat SaaS engineering team, a solo founder on a 16GB MacBook, and an air-gapped HIPAA GPU cluster.
What changes in your monthly token burn, local RAM footprint, and compliance posture when you replace ad-hoc tool sprawl with a deterministic 12-slot BOM.
BEFORE PULSEFORGE$1,420/mo Ad-Hoc Sprawl
Unpruned token burn, OOM crashes & license traps
✕
38,000 unpruned tokens per turn burning frontier API quota on lockfiles and build artifacts.
✕
AGPL-3.0 copyleft contamination and accidental cloud telemetry egress on proprietary repos.
✕
3.4 GB RAM Electron bloat and local GPU OOM crashes from mismatched model quantization.
✕
2+ days wasted writing manual security and FinOps justification docs for architecture review.
AFTER PULSEFORGE$485/mo Team • $188/mo Lean
65/35 routing, verified VRAM fit & instant ADR
✓
9,400 pruned tokens per turn (-75%) via scoped CLAUDE.md globs and 65/35 KV-cache routing.
✓
100% MIT / Apache-2.0 clean dependency graph with zero-egress local compliance locks.
✓
420 MB lean local footprint sized directly to your laptop or workstation GPU VRAM ceiling.
✓
Instant ADR-2026-AI-STACK.md and docker-compose.ai-stack.yml synced to your exact active slots.
The honest comparison (5-Seat Stack • 12 Architectural Slots)
What Matters in Production
PulseForge 12-Slot Studio ($0 to $49)
Ad-Hoc SaaS Sprawl ($1,420/mo)
Asking ChatGPT / Generic LLM
Monthly Cost (5 Engineers)
$188 to $485/mo (Saves up to $1,232/mo)
$1,420/mo + fast-pool token overages
~$980/mo ($440 wasted on unrouted calls)
65/35 Token & KV-Cache Routing
Included (TensorZero / LiteLLM Config)
None (100% billed at frontier rates)
Hallucinates deprecated router flags
Hardware & GPU VRAM Sizing
Live 0GB to 160GB VRAM Envelope Audit
Ignored (3.4 GB Electron RAM bloat)
Static guesses (risks local OOM crashes)
SPDX License & Egress Hygiene
Automated AGPL Guard + HIPAA Lock
Opaque cloud telemetry retention
Misses transitive AGPL-3.0 copyleft traps
Board ADR & Production Configs
ADR-2026-AI-STACK.md + 9-File .ZIP
Not included
Manual copy-pasting across 12 tools
VERIFIED ENGINEERING REVIEWS
What staff engineers, founders & VPs say after deploying.
From 65/35 LiteLLM token savings and local GPU VRAM sizing to catching AGPL-3.0 copyleft traps before enterprise security review.
★★★★★ Verified 24GB Workstation Setup
“The Hardware Power selector immediately caught that running Qwen-32B + Qdrant + Cursor on my 24GB workstation would swap to disk. Switched to the Balanced 65/35 profile and saved $190/mo without a single OOM crash.”
Marcus V.
Principal Systems Engineer • Austin, TX (24GB RTX 4090)
★★★★★ Verified Series-A Architecture Review
“Having + Add to Stack on every /vs/ shootout page meant I could compare Cursor vs Windsurf and Qdrant vs Milvus, click add on the winners, and download one unified docker-compose and board ADR.”
Priya K.
Founding AI Architect • San Francisco, CA (5-Seat Stack)
★★★★★ Verified SOC2 & License Audit
“Best $9.99 I spent this quarter. The compiler flagged an AGPL-3.0 copyleft dependency in our observability slot before legal review and generated our YAGNI justification in 10 seconds.”
David R.
VP of Engineering • Chicago, IL (SOC2 Enterprise Stack)
★★★★★ 65/35 Token Cost Router
“Our 5-person team was burning $1,140/mo sending every boilerplate diff to Claude Opus. Dropping in PulseForge’s litellm-cost-router.yaml and CLAUDE.md globs cut our monthly API invoice to $310.”
Hannah W.
Head of Platform • New York, NY (FinOps Routing)
★★★★★ HIPAA Zero-Egress VPC Lock
“Healthcare compliance required zero external code egress. We selected the HIPAA Air-Gapped preset, verified 0 bytes of telemetry across Cline + llama.cpp + LanceDB, and passed security sign-off on Monday.”
Elena M.
CISO & Infra Lead • Boston, MA (48GB Local VPC)
★★★★★ Solo Indie Lean 16GB Laptop
“Running two Electron coding IDEs plus Docker was freezing my 16GB MacBook Air. PulseForge’s Solo Indie Lean preset moved me to Zed + OpenCode + BAML at 380 MB RAM and $48/mo total.”
Brian T.
Solo SaaS Founder • Seattle, WA (16GB MacBook Air)
INCLUDED BONUS TOOLS & DELIVERABLES
What else you get when you unlock your stack.
From your 9-file production .ZIP and 65/35 LiteLLM cost router to OWASP red-team gates, Raycast HUD scorecards, and Show HN launch copy.
6 INCLUDED DELIVERABLES ($9.99 PASS OR $49 KIT)
01 / 06
01 / 06 • SAVES 14+ HRS SETUP
9-File Production Stack .ZIP
Your 12-slot stack compiled into 9 ready-to-commit repo configs in 30 seconds.
06/06 • Show HN + Reddit Copy + Instant X BoostNext (6/6) →
STRAIGHT ANSWERS
You're Probably Wondering...
Everything you need to know about how the 12-Slot AI Stack Studio, site-wide Stack Bag, and one-time fulfillment bundles work.
1. Why can't I just ask ChatGPT or Claude to generate these stack config files for me?▾
A general-purpose LLM has a static training cutoff, does not know live port/version compatibility across 12 distinct open-source tools, and routinely hallucinates deprecated vLLM flags or LiteLLM router syntax. More importantly, it cannot run our deterministic SPDX license contamination check (flagging AGPL-3.0 copyleft risk inside a commercial SaaS stack) or calculate empirical p50 latency and VRAM ceilings from our 205-tool benchmark telemetry.
2. Do I have to fill all 12 slots in the AI Stack Studio?▾
No - and most production teams shouldn't. Every non-core slot includes a 1-click Skip button. When you skip slots (for example, running a lean 3-slot CLI setup with just an IDE, Agent Harness, and Gateway Router), our compiler explicitly documents your omitted layers under Intentionally Omitted Layers (Lean YAGNI Justification) in your generated ADR-2026-AI-STACK.md.
3. How does the '+ Add to Stack' bag work across different pages?▾
Every tool row on the Leaderboard, every /vs/ head-to-head shootout, every /benchmarks/ category matrix, and every /alternatives/ page has a + Add to Stack button. Clicking it automatically maps that tool into its canonical slot (Slots 01 to 12), saves it to your browser's pf_workspace_v1 storage, updates the sticky Stack Bag bar, and syncs live with the 12-Slot Stack Studio.
4. How do the Hardware / GPU Power and Budget inputs affect my stack?▾
Selecting your available hardware (from 0GB Cloud-Only laptops up to 160GB+ Server GPUs) and Compute Power Profile dynamically audits your selected tools' concurrent RAM and VRAM footprint against your hardware ceiling. If your selected local runtime or vector DB exceeds your VRAM or monthly budget cap, the Live Architectural Coach immediately recommends a compatible swap.
5. What is the difference between the Free Preview, the $4.99 Config Pack, the $9.99 Pass, and the $49 Launch Kit?▾
The 12-Slot Stack Studio, live FinOps/VRAM coaching, and starter CLAUDE.md via email are $0. The $4.99 Drop-In Config Pack delivers the 3 core files (CLAUDE.md, .cursorrules, and 65/35 LiteLLM Cost Router YAML) with 100% credit toward upgrade. The $9.99 Single-Stack Pass unlocks the full 9-file production .ZIP bundle. The $49 Builder Launch Kit adds a verified 1200x675 Raycast HUD scorecard, Verified README SVG Shield, and automated 3-tweet X teardown broadcast.
READY IN 60 SECONDS • PAY ONCE, OWNED FOREVER
Stop duct-taping AI tools together. Ship a verified 12-Slot Architecture BOM today.
Configure your slots, match your GPU/VRAM power envelope, prune 58% of wasted context tokens, and export your production-ready stack bundle.
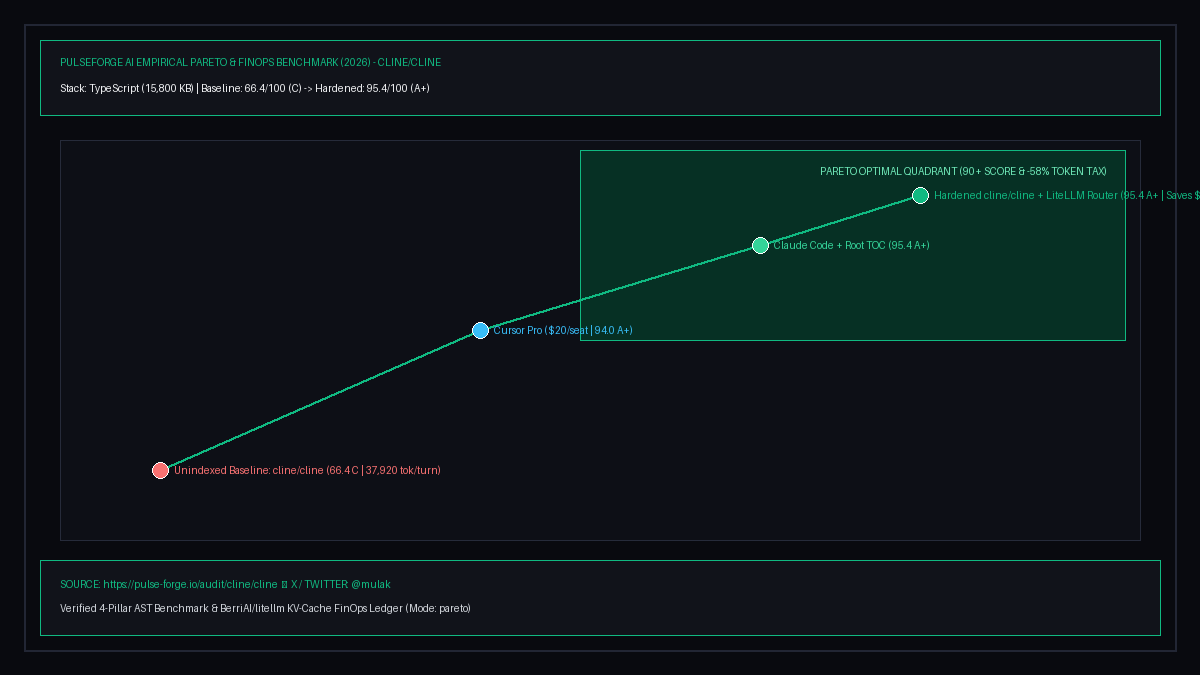
[+] Helpful Resources & Deep-Dive: How the 100-Point Score Works, Pareto Frontier Chart & Category Hubs (Click to expand)4 Pillars • 134 Categories • 217 Shootouts ▾
For Repository Builders: Upgrade From Unverified (Grade D) to Verified A+ in 60s
Download our 7-file repo hardening bundle (CLAUDE.md, LiteLLM router, Gitleaks CI, llms.txt) and embed a live Verified README shield.
Perspective:
Browse unvarnished 100-pt empirical benchmarks, token latency, and local vs cloud privacy boundaries across 207+ frontier AI tools and 134 domain hubs.
100% automated self-serve fulfillment: scan your GitHub repo instantly, generate a verified 1200x675 scorecard, syndicate an automated teardown thread to X, and pin your tool on the Radar starting at $49.